Where to Start with AI in Claims: Start Where Nobody Has to Change How They Work
If you’re trying to work out where to put AI first in a claims operation, start with file review, run on files you’ve already closed. Not because it’s small. Because it’s the one place you can prove the thing works without asking a single person to change how they do their job.
That last part is the whole ballgame, and it took me a while to understand why.
The question I get most from claims leaders isn’t whether to use AI. It’s where to put it first. And the standard answer everybody gives, including me for a while, is start small. Pick something narrow, get a win, use it to fund the next thing. That’s the easy answer. I’m not sure it’s the correct one.
Why most first AI projects in claims stall
What I’ve watched happen, more than once:
The pilot goes fine. The buyer sees the value, the numbers look good, everybody in the room nods. Then the thing gets rolled out to the people who are supposed to use it every day, and six months later you’ve got a handful of users and a lot of licenses. Nothing about the technology failed. The scope wasn’t too big. It just never made it past the two people who bought it.
Somebody who’s been in this industry for thirty years put it to me plainly a few weeks ago: when a person thinks their job is on the line, it’s tough to get them motivated, and that’s true of anything new, whether it’s AI or not. He’s right, and I’d go further. Adoption isn’t a step at the end of the project. Adoption is the project.
He also told me about an estimating platform that got rolled out across a large carrier years ago, and I haven’t been able to shake it. The vendor didn’t hand over the software and a training deck. They sat side by side with the carrier’s own trainers, hands on, for as long as it took. His view is that if they’d delivered the product and said good luck, that carrier would still be figuring it out. I think he’s right, and I think most of us in this business have been shipping the good luck version.
What that has to do with where you start
If adoption is the thing that kills these projects, the first question about a candidate project isn’t how big it is. It’s how much you’re asking people to change.
That reframes everything. A project that requires your adjusters to work differently is a change management program wearing a technology costume, and those take a year and a lot of goodwill you may not have. A project that runs alongside the way people already work has almost none of that drag, because nobody has to be convinced of anything before it can start producing.
Which is a long way of saying: pick the thing that doesn’t need permission from every person it touches.
Three questions I ask before any first AI project
When somebody asks me where to start, I don’t answer with a product. I ask them to run their candidates through three questions.
1. Does the standard already exist?
If you have to invent what correct looks like before software can help you, you’re not starting a technology project. You’re starting a policy project, and those take forever. Pick something where the right answer is already written down.
2. Can you check the answer?
Can a person look at the output and say yes that’s right, or no that’s wrong, in under a minute? If so, you’ve got a feedback loop and you’ll get better fast. If the only way to know whether it worked is to wait two quarters and read a report, you don’t, and you won’t.
3. Can you run it on work you’ve already done?
Closed files are the safest test there is. You know how they turned out, you can see exactly what the system would have caught and what it would have missed, and nobody’s Tuesday gets interrupted.
Most of the AI pitches in this industry fail at least one of those. A fair number fail all three.
Why claims file review passes all three
The standard already exists. It’s your carrier guidelines. Somebody wrote them, everybody is supposed to follow them, and nobody has to sit in a room negotiating what they mean before you can start.
The answer is checkable. A finding either points to a real gap in a real file or it doesn’t. Your reviewer opens the file, looks at the finding, and knows in about thirty seconds.
You can run it on closed files. Every carrier, IA firm, and restoration shop I talk to is sitting on a stack of files that are already done.
And then there’s the fourth thing, which is the reason I keep coming back to it. Files come in the way they come in today. The review runs alongside them. Your adjuster still makes the call. You’re not asking anybody to do their job differently in order to find out whether this works.
The part nobody budgets for: every carrier wants something different
There’s a wrinkle in “the standard already exists” that anyone who has run a review desk knows about. It isn’t one standard. An IA firm works for a dozen carriers and each one wants its own things: which photos have to be in the file, what the headers and forms have to include, which line items are allowed, which are depreciable and which aren’t, what has to be provided to the onsite contact.
That adds up to hundreds of combinations of rules and guidelines, and those combinations are what actually decide whether an estimate package is correct. Carriers carry a version of this too. For IAs, TPAs, and restoration contractors who estimate for several carriers at once, it’s the whole job.
Today that load sits on people. A reviewer is supposed to hold all of it in their head and apply the right set to the right file, every time, at four in the afternoon. The field adjuster is supposed to have built the file to that same set in the first place. When something slips, it usually isn’t carelessness. It’s that nobody can hold hundreds of rule sets at once.
That’s the part QA Complete takes. The rules are set up around your guidelines during onboarding, and every file gets checked against the right set for that carrier. Your reviewers don’t have to carry it, and nobody on your team is asked to write rules or maintain a rules engine. That part is ours.
What this looks like on one file
The version that makes it concrete:
A reviewer flags a missing line item and sends the file back to the field adjuster. Two days go by. The field adjuster replies that it was documented all along, it’s sitting right there in the general loss report. So the file goes back to review. Nothing was actually wrong. The file just moved twice for no reason and the policyholder waited four extra days on money they were owed.
That loop happened for a boring reason. The person reviewing the file and the person who built it were reading different parts of it. That’s the gap between the standard on paper and the standard on the file, and it runs both directions. The same blind spot that sends a clean file back is the one that lets a real miss go out the door.
A review that reads the whole packet together, the photos and the estimate and the scope and the documentation all at once, doesn’t send that file back. Multiply it across a few thousand files a year and you’ve got a decent chunk of what people are calling a cycle-time problem.
We have this problem too
I’d rather say this out loud than have you find it out on your own.
We have customers who bought our platform and haven’t rolled it out to their full team. Not because it doesn’t work for them, and not because they changed their minds. Because getting a group of busy people to pick up something new is hard, and for a stretch there we were handing over a login and a training session and expecting the rest to take care of itself. That’s on us, and I don’t think we’re alone in it. I think it’s close to standard practice in claims tech right now.
What I can tell you is what the accounts that work look like, because the pattern isn’t subtle.
They look like the restoration customer we’re on a call with every single week, going through the actual files they pushed through the platform, reviewing findings together. Their user managers have been in there with us while we set it up around their environment. They’re running their own internal training and they asked us to train their trainer. That isn’t a customer we sold and walked away from. That’s a customer we’re in the file with.
So that’s how we run an implementation now. Not a login and good luck. Weekly, in the files, with your people, until your team is comfortable and using it without us in the room. If we see adoption lagging, we come find out why rather than waiting for it to show up on a renewal call.
I don’t have a clean number to put on any of that yet. We’re in the middle of sitting down with our own customers to understand exactly where the friction is, and I’d rather tell you that than make something up.
How to run a closed-file pilot
If you’ve got budget and a mandate and no first project, this is the whole sequence.
- Pull a batch of closed files. Enough to be representative. Mix in some clean ones and some you know had problems.
- Send your guidelines with them. Whatever your reviewers are already held to. You don’t need to write anything new.
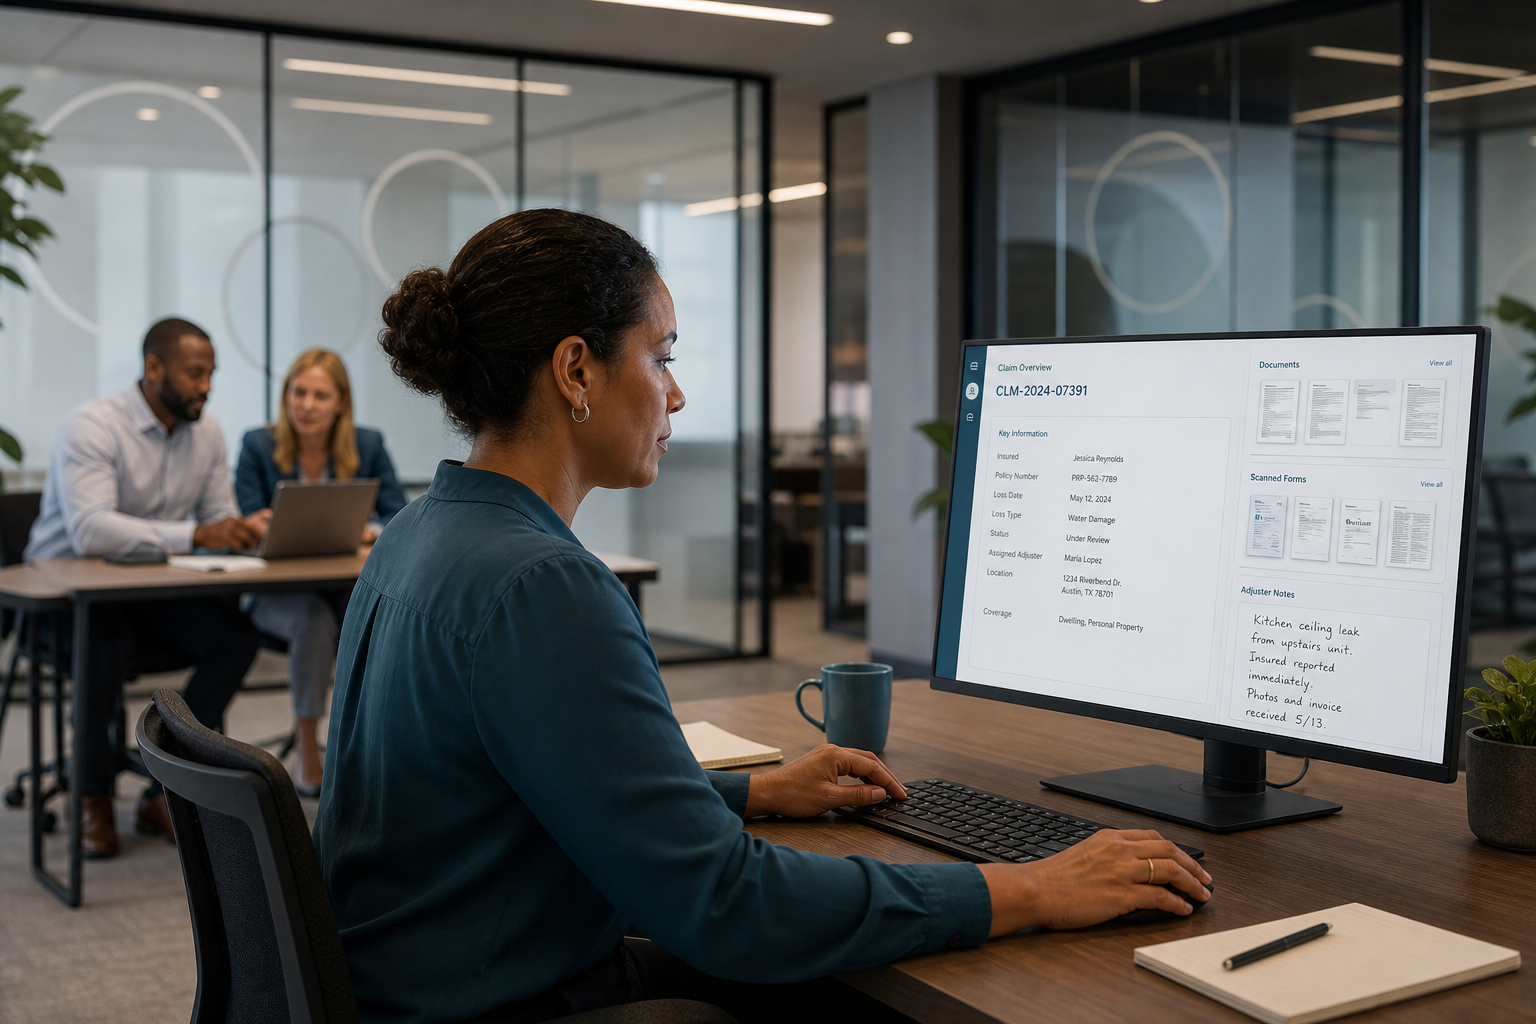
- We review the full packet on every file. Photos, estimate, scope, and documentation, read together instead of in pieces.
- You get findings that name the rule, show the math, and point to the evidence. Every finding traces to a specific line in your own guidelines and a specific place in the file.
- Your reviewers grade it. What it caught, what it missed, and what it flagged that it shouldn’t have.
- You decide whether it’s worth more. Nothing about your workflow changes while we do it.
That’s the whole ask, and you don’t have to believe a word I’ve written here. Run it on your own closed files and find out.
What we see when we run it
A thorough manual review of a complete file runs well over an hour on most desks. QA Complete reads the whole file, the general loss report and the estimate included, and hands back about 45 minutes per review, roughly 60 percent of the time it takes today. Processing a file takes four to five minutes. Most teams are set up and running in about three weeks.
I’m not 100% convinced speed is the interesting number, by the way. The one I’d watch is how many files stop making a second lap, and whether the people who are supposed to be using this are actually using it ninety days later. That second one is the number almost nobody asks a vendor about, and it’s the one that decides whether any of this was worth doing.
Frequently asked questions
What is AI claims file review?
AI claims file review reads a complete claim packet, including photos, the estimate, the scope, and the supporting documentation, and checks it against your carrier guidelines. It returns findings that name the rule, show the calculation, and link to the evidence in the file. It doesn’t decide the claim. It tells a human reviewer where to look.
Where should an insurer start with AI?
Start with file review on closed files. It’s the only common claims workflow where the standard is already documented, the output is verifiable in under a minute, and the whole thing can run on past work without asking anyone to change how they do their job.
Why do AI projects in claims fail?
Usually adoption, not technology. The buyer sees the value and the daily users never pick it up, most often because nobody stayed in the workflow with them after implementation. Ask any vendor what happens in the ninety days after you go live.
What if every carrier we work for wants something different?
That’s the normal case, and it’s the reason this is hard to do by memory. Photos, forms, allowed line items, what’s depreciable, what the onsite contact needs: it runs to hundreds of combinations across a book of carriers. Your rule sets are built around your guidelines during onboarding, and each file is checked against the right one, so your reviewers aren’t holding it all in their heads.
Is it safe to run AI on real claim data?
I spent the decade before this building a data security company, so it’s the question I’d ask first too, and it deserves a better answer than a paragraph in a blog post. Before any pilot we’ll take your security and legal teams through how claim data is handled, what our model providers can and can’t do with it, how long anything is kept, and who can see it. Ask us for that in writing. Ask every other vendor on your list for the same thing, and compare the answers.
Do adjusters have to change how they work?
No, and that’s the entire reason I recommend starting here. Files come in the way they come in today and the review runs alongside them. The adjuster still makes the call.
Alex Pezold is a co-founder of Agentech, which builds AI claim oversight for carriers, IAs and TPAs, and restoration companies. He previously founded and scaled TokenEx, a data security platform, through its exit in 2021.